All projectsAevonix Research / Project
Autonomous Extended Volitional Agent.
A.E.V.A. is our research into voice, vision, embodiment and out-of-model-weights recursive learning.
She runs on Hermes and Protagine. We also build and test her embodiment hardware for physical interaction.
In development
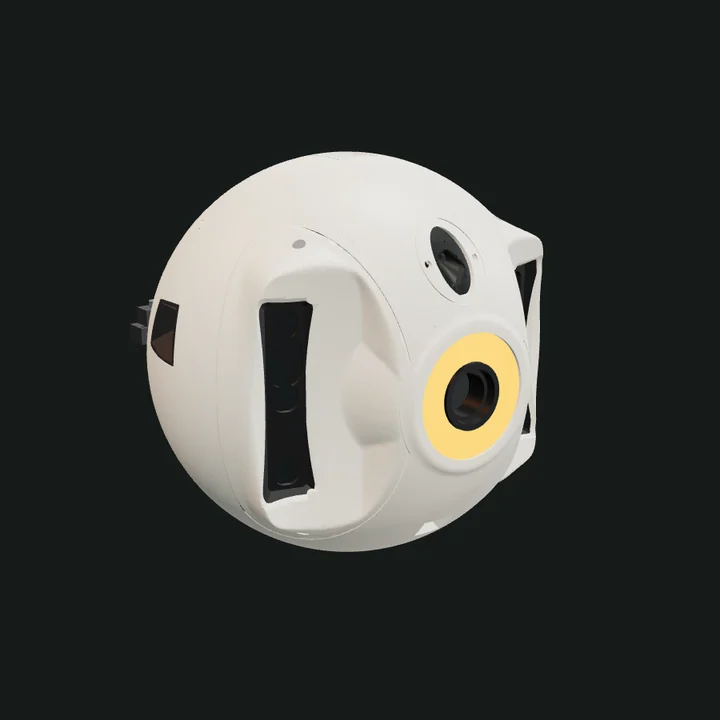
Embodiment prototypeDesign in progress
Rendered from our prototype CAD. Parts are separated for illustration.
Functional overviewSelect a component
Hermes coordinates the work.
Hermes runs the agent, brings in context, calls tools and coordinates model requests. A separate Mac runtime hosts orchestration and integrations.
- Agent execution and tool use
- Requests to local model services
- Memory and continuity through Protagine
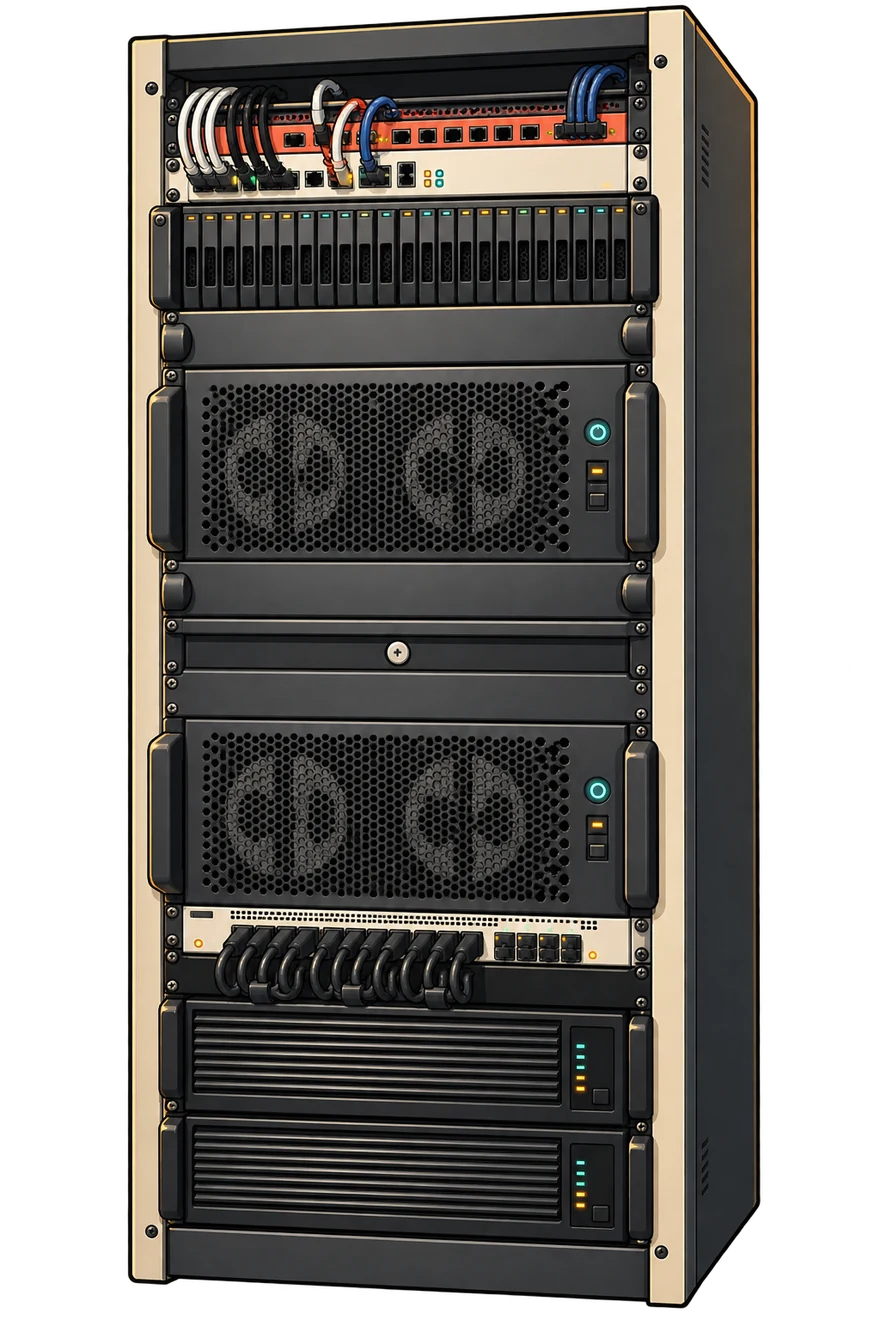
4 × RTX PRO 6000 Blackwell
Upper STEIGER DYNAMICS chassis
Primary local language and scene-understanding inference. The recorded GLM configuration uses two GPUs; four GPUs are installed in the server.
- GPU memory
- 4 × 96 GB · 384 GB installed
- Processor
- AMD Threadripper PRO 7975WX
- Assigned model
- GLM-5.3-Flash
Model assignments reflect the September 2026 research configuration. Installed hardware can be allocated across several workloads.
Language & visionGLM-5.3-Flash
Primary local language model and scene-understanding service.
RTX PRO 6000 Blackwell server
Long-context workKimi K3
Distributed local inference for longer-context, bulk and fallback work.
16-node DGX Spark workload
Speech recognitionNVIDIA Parakeet TDT 0.6B v3
Converts microphone audio into text for the agent.
Local speech-recognition service
Speech generationVoxCPM2
Turns the agent’s response into speech for playback.
Local speech-generation service
Memory embeddingsQwen3-Embedding-8B
Builds vector representations used to find relevant stored context.
Memory retrieval service
Memory rerankingQwen3-Reranker-8B
Orders retrieved candidates by relevance before they are used as context.
Memory retrieval service
04 / Sensing & embodiment
Seeing, hearing and responding.
The documented sensor interface uses a Pixel 8 Pro for camera and audio. Our spherical head and Z1 Pro arm are a separate embodiment prototype.
Camera
Selected Pixel 8 Pro camera frames feed GLM scene understanding.
Microphone
Audio feeds Parakeet speech recognition, then the agent’s processing.
Speaker
VoxCPM2 generates speech for audio playback through the speaker interface.
Prototype researchA.E.V.A. head + Unitree Z1 Pro
The head and arm are in development. The prototype viewer shows the mechanical design we are building and testing.
Explore the head prototype Research configuration / September 2026
Project enquiriesMaggie@aevonix.com